OpenAI’s latest speed claim is easy to misread. The company has not released a new model called Ultrafast. It has opened a limited API preview of a new service tier that serves its existing GPT-5.6 Sol model at up to 14 times the speed of Standard processing, with a stated peak of 750 output tokens per second. The tier is powered by Cerebras hardware.
That matters because response delay is often what stops an AI demo from becoming part of a business process. A reply that takes half a minute can still be useful for a product description. It is much harder to use in a customer conversation, a live voice workflow, or a troubleshooting loop where each next step depends on the previous answer. But the announcement does not mean a neighbourhood retailer can switch on a faster ChatGPT today. Access is limited, the product is API-only, and the relevant question is not whether 14x sounds impressive. It is whether a particular workflow loses money or customer trust while waiting.
🚀 What OpenAI actually announced
OpenAI announced the Ultrafast preview on August 13, 2026. It describes the offering as a service tier for GPT-5.6 Sol, rather than a separate model family. The headline numbers are “up to 14x faster” than Standard processing and up to 750 generated tokens each second. Those are performance claims, not a promise that every prompt will finish in one fourteenth of the usual time.
A model response has several moving parts. A system has to receive a request, process the input, begin generating, call any tools required by the application, and send the completed answer back to the user. A speed figure can refer mainly to token generation after the model starts responding. It does not erase network delay, a slow CRM integration, a database query, a human approval rule, or a customer who has not supplied an order number.
OpenAI says the preview is aimed at workloads where latency has direct operational value. Its examples include incident response, developer agents, customer support and voice, financial research, fraud detection, and e-commerce. Those examples are useful for thinking, but they are not case studies proving a return for every business.
Reporting from The Next Web adds detail worth carrying into a business read: early testers named in the preview, including Jane Street, Podium, Basis, and Rogo, described the change as qualitative, not incremental. One tester is quoted saying speed "completely changes the call experience for complex work" and unlocks "synchronous experiences for users that were previously limited by intelligence." That framing is a hint about where value tends to appear: not in every task, but specifically in ones where a person is waiting live on the other end, such as a phone call, a chat, or an active troubleshooting session.
The practical first reading is therefore narrow: an already capable model can be served much faster for a limited set of API customers. It is not a new consumer feature in the ordinary ChatGPT app. It is not a guarantee that an agent can make safe decisions without oversight. And it is not a general availability announcement for Indonesia. A business owner reading the headline should separate three different claims that are easy to blur together: the model got smarter, the model got cheaper, and the model got faster. Only the third claim is what this announcement actually makes.
⚡ Why speed changes the shape of an AI workflow
For a person writing an occasional email, waiting is annoying but manageable. For a multi-step system, waiting accumulates. Consider a support assistant that must read a customer’s message, retrieve a policy, check stock, draft a response, pass that draft through a tone rule, and offer a human handoff. A pause at each stage makes the whole exchange feel hesitant even if each individual answer is accurate.
This is why speed has become a product property, not a benchmark footnote. A faster answer can keep a customer inside a conversation. It can let an operator test several wording options while a campaign is still being built. It can help an engineering team inspect a fresh incident log before the evidence becomes stale. None of that requires magical intelligence. It requires the rest of the workflow to be ready for a response at that pace.
There is also a downside. A quick wrong answer reaches a customer more quickly. A fast agent can create duplicate tickets, quote an outdated price, or make a refund promise that staff did not authorize. The value of lower latency rises when the business has a clear data source, bounded permissions, and a safe route to a person. Without those, faster generation can simply accelerate a messy process.
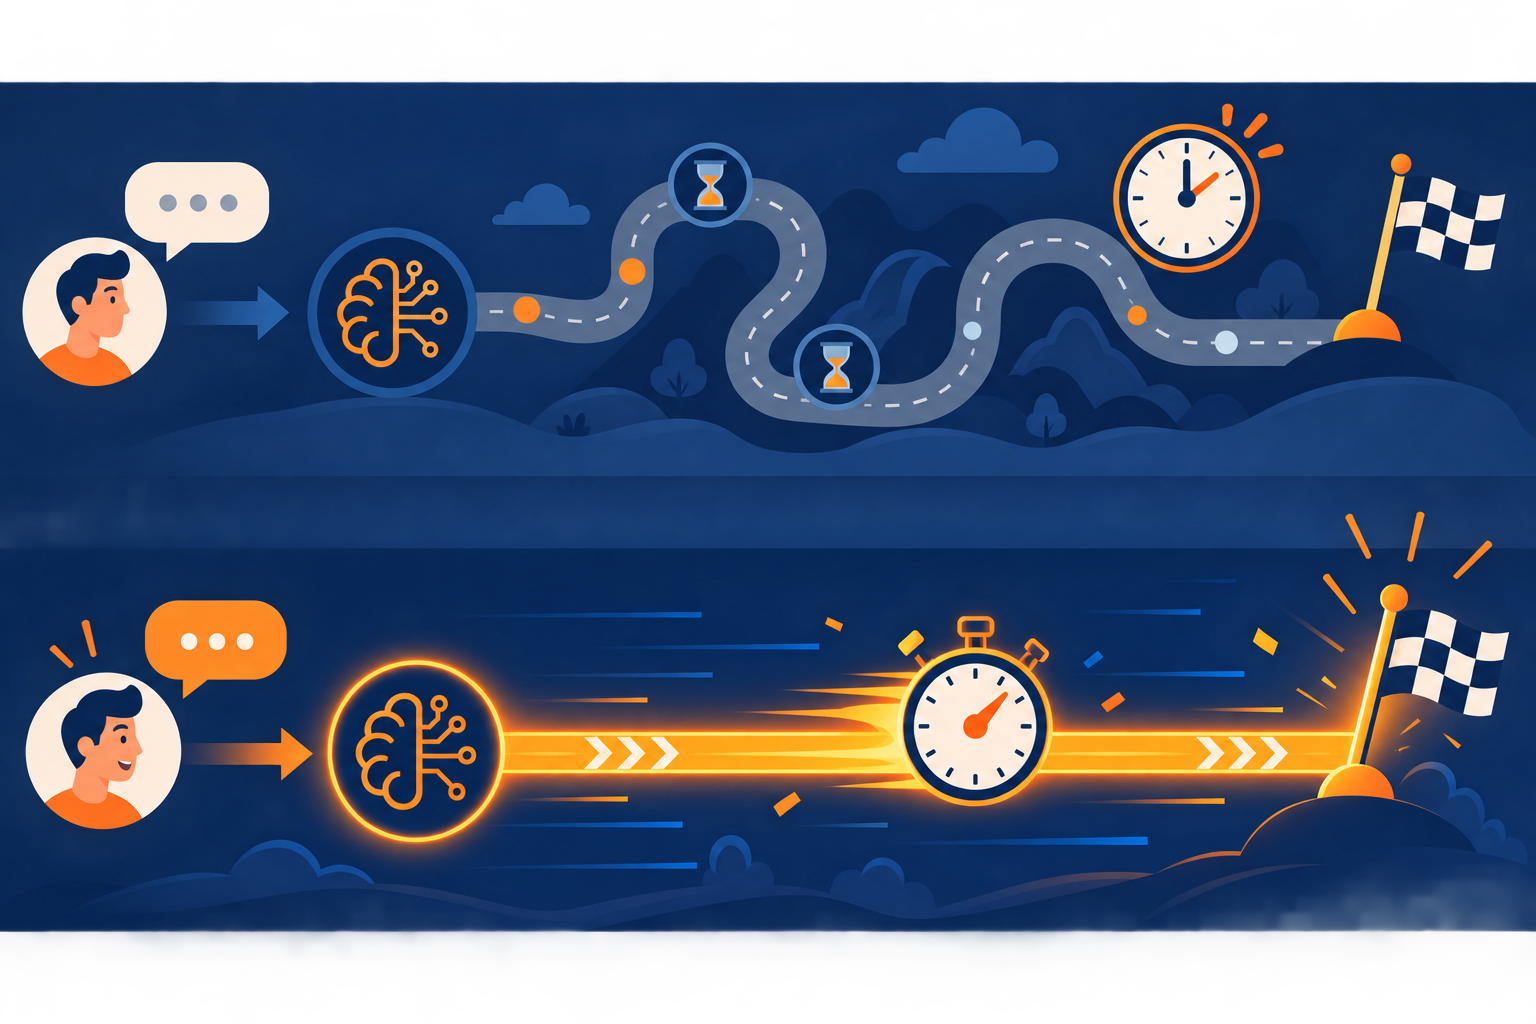
The useful test is to measure the full task. Track the time from a customer’s first message to a correct, approved outcome. If a human still needs ten minutes to validate payment, arrange delivery, or resolve an exception, a sub-second model reply will not turn that process into an instant service. It may improve the first response, which is different and still potentially valuable.
🖥️ The hardware story behind the headline
OpenAI says Ultrafast runs on infrastructure provided by Cerebras. Earlier in January 2026, OpenAI announced a Cerebras partnership intended to add 750 megawatts of high-speed AI compute. The current preview is the visible application of that broader effort to reduce inference latency.
Most public discussion of AI chips focuses on training: the expensive process of creating or substantially updating a model. Inference is different. It is the repeated work of producing an answer once a model exists. Customer-service chats, code suggestions, voice assistants, and product-search helpers all create inference demand. For a business using an API, inference delay is the delay the customer feels.
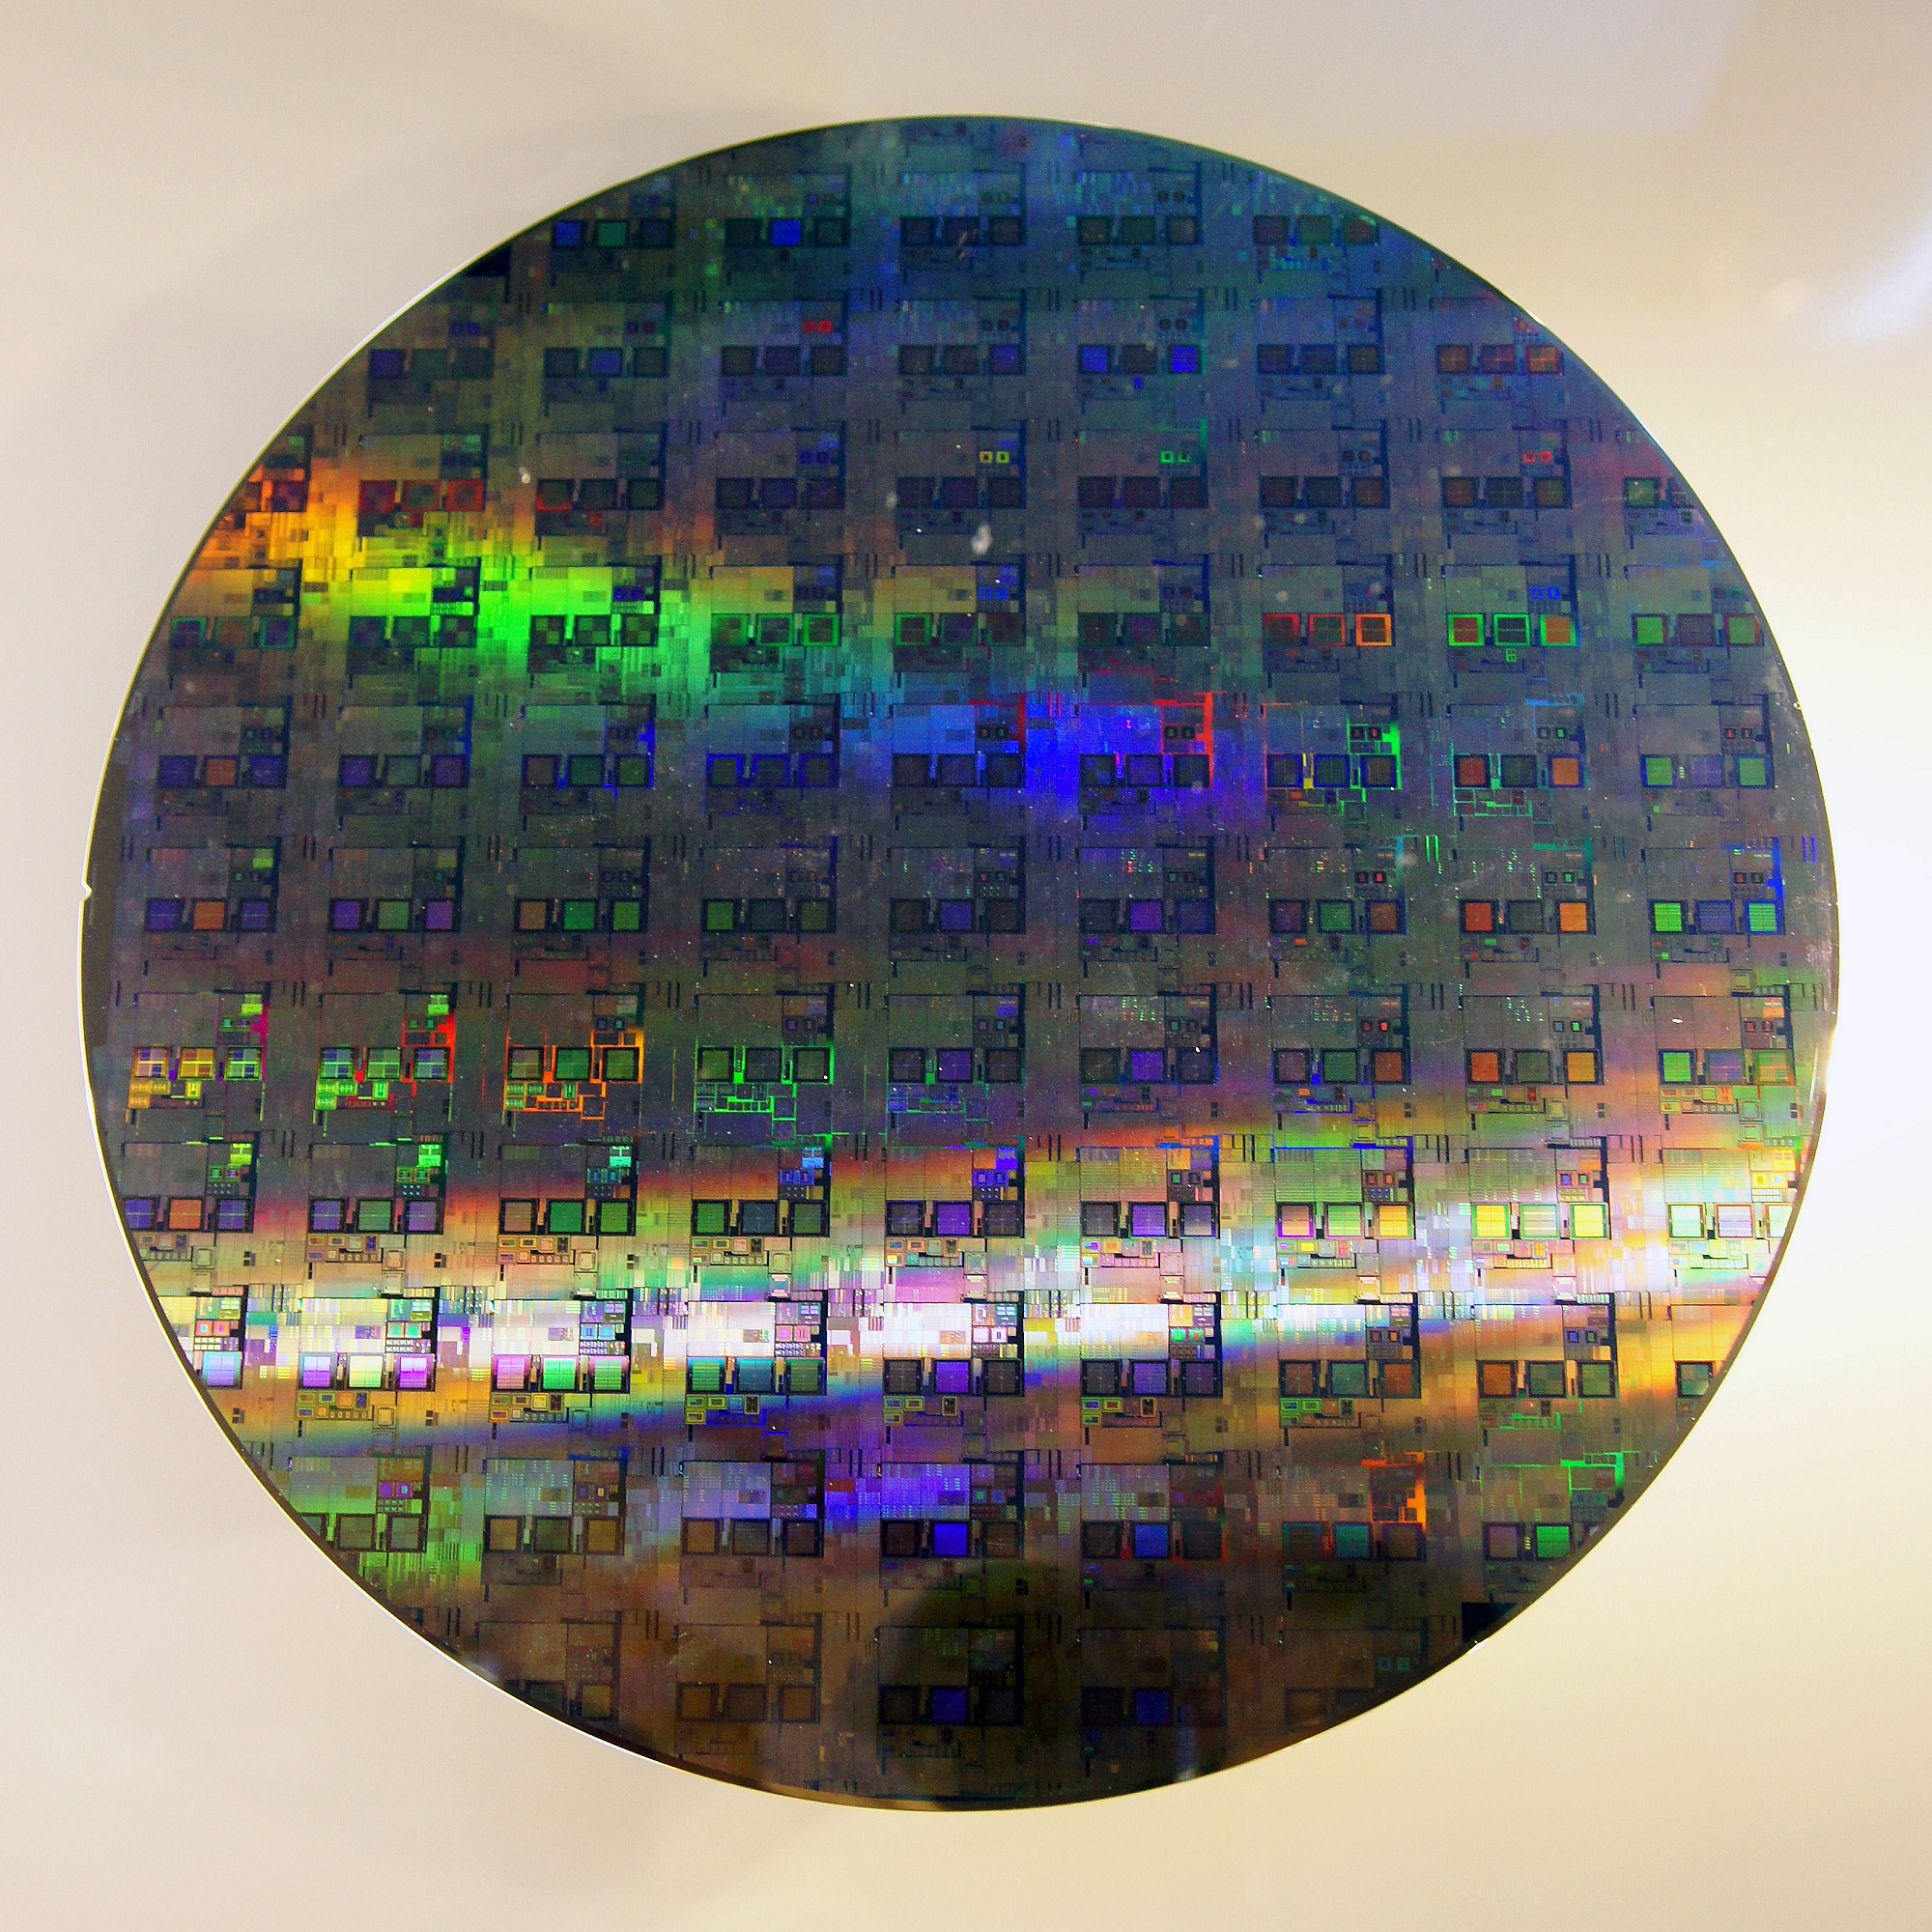
Cerebras is known for wafer-scale systems. Its approach places unusually large amounts of compute on a single wafer-scale processor rather than dividing a model across many conventional accelerators. The claimed advantage for some inference tasks is less data movement between separate chips and therefore less waiting before the next token appears. That is the engineering context for OpenAI’s speed claim.
Do not turn this into a hardware shopping decision for a small business. A small retailer cannot buy its way into the preview by purchasing a chip. OpenAI is selling access to a hosted tier. The hardware discussion matters because it explains why a model may become faster without becoming a different model. It also explains why capacity is limited: real-time infrastructure is not infinitely available simply because an API page exists.
🔐 Who can use Ultrafast today
The answer is deliberately restrictive. OpenAI says the tier is in limited preview for a small group of customers. Reporting from TechCrunch, 9to5Mac, India Today, and The Next Web consistently describes an application or waitlist process while capacity grows. An owner should not present the tier as available to a client unless their organization has a written access confirmation in its own API account.
That restriction changes the immediate action for most Indonesian businesses. There is no practical migration to execute today. There is a workflow to document. Identify where a slow AI response currently creates a visible problem, collect a few weeks of baseline data, and define what would count as an improvement if access later becomes available.
A business that already calls a model API can prepare a controlled test. Keep the same prompt, knowledge source, escalation policy, and user interface. Change only the service tier. Compare first-token delay, time to completed answer, rate of human intervention, customer abandonment before a reply, and the cost per successfully resolved conversation. The point is to detect a meaningful business effect rather than celebrate a technical metric.
A business that uses only consumer chat applications has even less to change. It should not rebuild its process around a preview it cannot access. Its better investment is an accurate product catalogue, an approved FAQ, a clear handoff route, and a method for keeping prices and stock current. Those assets remain useful with any model or provider.
💬 A customer-service use case, with boundaries
A seller receives the same questions every day: Is this colour in stock? What is the delivery estimate? Can I change the size? Does this price include shipping? A fast assistant can draft answers from a maintained catalogue and immediately ask for missing information. That can make a chat feel attended even before a team member joins.
The boundaries are more important than the speed. The assistant should not confirm a bank transfer, promise delivery before inventory is checked, approve a return outside policy, or improvise a discount. It should identify the question, retrieve approved information, make the next permitted request, and hand off exceptions. If a buyer shares a payment screenshot, a business still needs a proper reconciliation process; a fluent model response is not proof of funds.
A sensible trial is deliberately boring. Pick one narrow question category, such as store hours or product specifications. Use the exact text from an approved source. Run it during a defined window. Have staff review a sample of conversations. Stop if the assistant starts inventing facts or if customers receive different answers to the same question.
Latency becomes meaningful when the reply is both fast and dependable. A three-second response with the right stock status can reduce needless waiting. A one-second response with yesterday’s stock status can create a bigger problem than a ten-minute delay.
🎙️ Voice, agents, and the temptation to automate too far
OpenAI’s examples include voice and agentic workflows because these are especially sensitive to delay. People notice gaps in a spoken exchange quickly. An agent that must call several systems also feels slow when each planning step produces a long pause. Faster inference could make those experiences more natural.
It does not make them automatically safe for a small business. Voice adds transcription errors, background noise, accents, privacy concerns, and the risk of a caller misunderstanding an automated answer. Agents add a different risk: they can take a series of actions instead of merely producing text. The permissions for viewing an order, editing an address, issuing a refund, and changing inventory should not be treated as one permission just because a model is fast.
Set the authority first. An assistant can read a public delivery policy. It can collect an order number. It can propose a response for staff review. It should not change a payment status or send money unless the business has built explicit controls around that action. Lower latency does not replace audit logs, role-based access, or a person accountable for exceptions.
For many small teams, the best first agent is not an autonomous one. It is a fast draft-and-route tool: classify the request, surface the relevant record, suggest a reply, and leave the final action to the operator. That design gains some benefit from speed without betting the business on unattended automation.
There is a second, quieter risk worth naming: speed can make a bad process look acceptable for longer than it should. If an assistant answers instantly but with the wrong stock count, a customer may act on that answer before anyone catches the error. A slower system sometimes gives staff an accidental buffer to notice a mistake before it reaches the customer. Removing that buffer through speed is only safe once the underlying data and rules are trustworthy on their own.
💰 Cost, capacity, and the missing price question
OpenAI’s announcement describes performance and preview access, but an owner should not assume a lower wait time comes at the same price as Standard processing. Faster infrastructure can carry a premium. Anthropic’s February 2026 Fast Mode announcement is a useful reminder: its company described the 2.5x-faster option as more expensive to run and positioned it for urgent work.
The exact Ultrafast rate, terms, and quota available to a particular customer must come from that customer’s current OpenAI account and agreement. Do not estimate a monthly bill by multiplying a social-media headline by a guessed conversation count. Token usage varies with prompt length, retrieved documents, output length, retries, tool calls, and guardrail checks.
Build a cost table before a pilot. Include API input and output charges, engineering time, monitoring, storage for logs, integration fees, customer-support review, and the cost of errors. Then compare that total with the value of the task being improved. A fast response matters more for a high-value inbound lead or a stalled checkout than for an internal summary that nobody needs until tomorrow morning.
Capacity also matters. A limited preview can have usage caps, changing access, or performance that differs under load. A business should keep a fallback tier and a human fallback. The customer should never be left with a broken service because an experimental speed tier reached a limit.
There is a currency question too, and it is not optional. Most API billing from major providers runs in US dollars, converted at whatever rate applies when the invoice is issued. A rupiah-denominated small business should model that exposure explicitly rather than discover it on the first bill. A cost table that looks acceptable at one exchange rate can look different a quarter later, so building in a margin for currency movement is part of an honest pilot budget, not an afterthought.
🧪 A four-week pilot that produces evidence
A useful pilot does not need a large budget. It needs a stable scope. Start with a single workflow that has enough volume to measure and a low consequence if the system hands off. Product availability questions, appointment pre-screening, or routing common support requests are better candidates than payment disputes or medical advice.
Before the pilot starts, write down the guardrails the assistant must respect:
- Answer only from the approved product catalogue, policy document, or FAQ, never from memory or guesswork.
- Never confirm a payment, issue a refund, or promise a delivery date without a system check.
- Hand off to a person immediately when the question falls outside the defined topic list or the customer asks for a human.
- Log every conversation so a reviewer can audit accuracy after the fact.
In week one, write the baseline. Measure median first reply time, time to resolution, percentage of chats handed to a person, repeat contacts, abandoned chats, and errors found in review. Preserve a sample of real requests after removing information you do not need. Define the answer source and name the staff member who owns it.
In week two, run the existing tier with a fixed prompt and a simple review process. In week three, if the faster tier is actually available, run a comparable sample through it without changing the policy or knowledge base. In week four, compare outcomes. Do not compare a busy holiday week with a quiet weekday and call the difference model performance.
The decision rule should be written before launch. For example: continue only if first response time falls by a chosen amount, accuracy stays above the team’s threshold, no high-severity policy breach occurs, and the additional cost per resolved request remains acceptable. If no rule is met, stop. A stopped pilot with clean notes is useful evidence, not a failure.
🚫 What this announcement does not prove
The announcement does not prove that GPT-5.6 Sol is more accurate in Ultrafast mode. It does not prove that a 750-token-per-second figure will reach every user. It does not prove that a customer-support agent will solve more tickets, that an e-commerce store will convert more buyers, or that a model can be trusted with sensitive decisions.
It also does not settle the wider competition among AI providers. Anthropic, Google, and other providers are working on their own combinations of model capability, price, latency, and tools. A small business does not need to predict a winner. It needs an interface that can be tested, a way to move its approved knowledge, and records that show whether a tool helped.
Treat every "x times faster" figure in this market the way a careful buyer treats a fuel-economy sticker: a lab measurement under specific conditions, useful for comparison, not a guarantee of what happens on a particular route. A 14x claim was measured somewhere, under some load, with some prompt shape. Your workload will have its own bottlenecks, and some of them, like a slow internal API or a manual approval queue, have nothing to do with the model at all. Ask a vendor for the conditions behind a headline number before treating it as your own expected result.
There is a privacy limit too. Faster inference does not change the basic question of what data leaves the business and what terms apply. Before connecting customer chats, invoices, or internal documents to any API, read the current data controls, retention options, contract terms, and access rules. Remove sensitive information when it is not necessary for the task. Keep production credentials out of prompts and shared documents.
That quote describes a direction, not a result already earned by a particular merchant. The right response is interest plus verification. Ask for access details, technical terms, prices, and measured output from the actual account that would run the work.
✅ The practical decision for Indonesian small businesses
Most Indonesian small businesses should put Ultrafast on a watchlist, not a procurement list. The tier is limited-preview API infrastructure. There is no announced general Indonesian rollout, no consumer-app switch to activate, and no evidence yet that it lowers costs for ordinary business conversations.
The businesses that should prepare now are those with an existing API workflow and a measured latency problem. A live support queue, a voice assistant, a developer incident process, or a high-volume commerce flow may justify an application when access expands. Even then, the test should protect customer data, limit automated authority, retain a human fallback, and compare the full task outcome rather than token speed alone.
For everyone else, the immediate work is unglamorous and durable. Clean the product data. Decide which questions an assistant may answer. Make escalation visible. Track errors. Keep a human responsible for payment, delivery, refunds, and exceptions. When faster model access reaches the market, those foundations will decide whether it becomes a useful service improvement or merely a faster way to make the same mistakes.
None of this requires waiting passively. A business can write its escalation rules, document its FAQ, and set its measurement plan this month, using whatever model access it already has, whether that is a Standard-tier API account or a consumer chat subscription. When a faster tier eventually opens more broadly, the business that already has clean data and clear rules will capture the benefit in days. The business still cleaning up its catalogue will spend that same window fixing avoidable mistakes instead.
Sources: OpenAI, “Previewing Ultrafast mode” and “OpenAI partners with Cerebras,” January and August 2026; TechCrunch, 9to5Mac, India Today, and The Next Web reporting on the preview; Times of India reporting on Anthropic Fast Mode. Accessed August 14, 2026.
Official video source: OpenAI on YouTube, “Previewing Ultrafast mode: GPT-5.6 Sol at up to 14X the speed.”